Social listening API: one script for Reddit, X and YouTube
- Three searches on a daily schedule are enough to watch a brand on Reddit, X and YouTube. One run on September 30, 2026 for three developer-tool brands found 397 unique mentions from the last 24 hours in 25 calls and 74 seconds.
- Filter replies out of X or they'll bury everything else. A plain search for Supabase came back with 19 replies in its first 20 tweets, all from the last 75 minutes.
- Reddit and X results almost always name the brand; YouTube's mostly don't. 91% of Reddit posts and 92% of tweets had the brand in their text, against 8 of 50 YouTube titles.
- Re-read the whole day on every run and skip IDs you've seen. A second run nine minutes later found 9 new mentions, and 6 of them were hours old: posts the first run's searches hadn't returned.
- You give up sentiment scoring and history. The script only sees the last day, and it doesn't tell you whether a mention is angry or happy.
Built on AnyAPI
409 scraping and data APIs behind one key.
Every endpoint in this post is one call away. Pay per request in USD from a prepaid wallet, with automatic failover when a provider breaks. No subscription, no card to start.
Get ~150 free requests$0.10 of credit on signup.Somebody at your company wants to know when people talk about the product. Maybe it's a founder who keeps finding Reddit threads a week late, or a support lead who wants to catch the "is this down for anyone else?" tweets. The usual answer is a social listening tool at a few hundred dollars a month. If what you actually need is a list of new mentions in a Slack channel or a log file every morning, you can write it yourself.
A social listening API here just means a search endpoint you call on a schedule and diff against what you've already seen. This post gives you a script that does that for Reddit, X and YouTube through three AnyAPI search endpoints, and shows what one real day of it returned on September 30, 2026 for Supabase, PostHog and Raycast: how many mentions, how many were noise, how many were repeats, and what it cost.
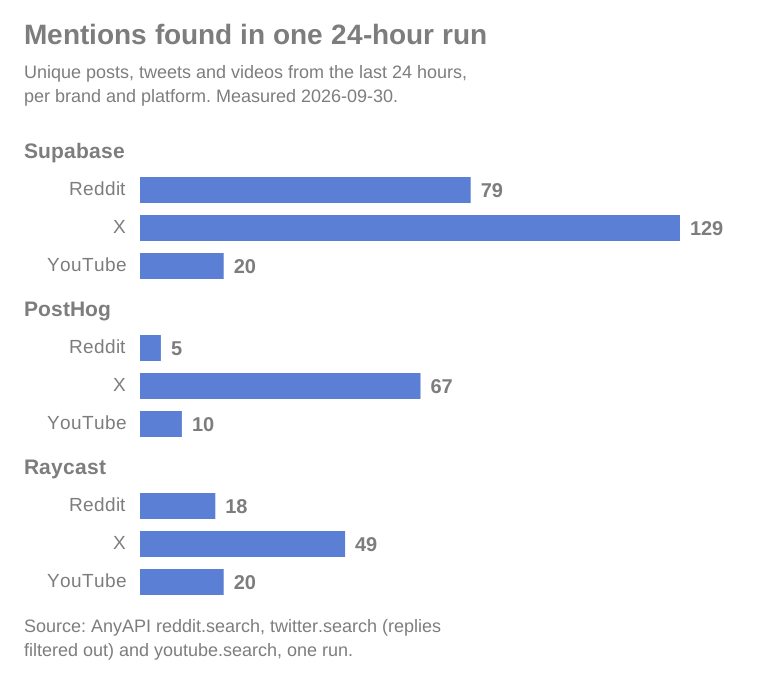
| Brand | Reddit posts | Tweets (no replies) | YouTube videos | Calls |
|---|---|---|---|---|
| Supabase | 79 | 129 | 20 | 13 |
| PostHog | 5 | 67 | 10 | 6 |
| Raycast | 18 | 49 | 20 | 6 |
| All three | 102 | 245 | 50 | 25 |
At a glance
| Question | What one day of data says |
|---|---|
| How many mentions in a day? | 397 unique for three brands: 102 on Reddit, 245 on X, 50 on YouTube |
| Which platform is loudest? | X, for all three brands. Supabase alone had 129 tweets without replies |
| How much of it is about the brand? | 91% on Reddit, 92% on X, 16% on YouTube, by whether the text names the brand |
| How many calls does a run take? | 25: one to seven per search, depending on how busy the brand is |
| How long does a run take? | 74 seconds, one call at a time |
| What does a second run the same day return? | 400 results, 391 already seen, 9 new, for the same 25 calls |
| What does it cost? | $0.013 for the 25 calls |
How do you build a social listening script for Reddit, X and YouTube?
A social listening script for Reddit, X and YouTube is three searches and a list of IDs you've already seen: the 64 lines below run each search for the last 24 hours and print only results whose ID isn't on the list. It needs Python 3 and nothing else. Save it as listen.py, put your brand names in BRANDS, set ANYAPI_API_KEY, and run it.
"""Print new mentions of each brand on Reddit, X and YouTube from the last 24 hours."""
import json
import os
import pathlib
import time
import urllib.request

BRANDS = ["supabase", "posthog", "raycast"]
SEEN = pathlib.Path("seen.json")
DAY = 86400


def run(sku, body):
    req = urllib.request.Request(
        "https://api.getanyapi.com/v1/run/" + sku,
        data=json.dumps(body).encode(),
        headers={
            "Authorization": f"Bearer {os.environ['ANYAPI_API_KEY']}",
            "Content-Type": "application/json",
            "User-Agent": "brand-listener/1.0",
        },
    )
    with urllib.request.urlopen(req, timeout=120) as resp:
        return json.load(resp)


def search(sku, body, rows, since):
    """Yield one search's results, page by page, until they're older than `since`."""
    cursor = None
    while True:
        res = run(sku, {**body, "cursor": cursor} if cursor else body)
        page = res["output"].get("data") or {}
        items = page.get(rows) or []
        yield from items
        dates = [i["createdUtc"] for i in items if i.get("createdUtc")]
        cursor = page.get("nextCursor")
        if not cursor or not dates or min(dates) < since:
            return


def mentions(brand, since):
    for p in search("reddit.search", {"query": brand, "sort": "new", "timeframe": "day"}, "posts", since):
        yield "reddit", p, p["title"], "https://www.reddit.com" + p["permalink"]
    for t in search("twitter.search", {"query": f"{brand} -filter:replies"}, "items", since):
        yield "x", t, t["text"], t["url"]
    for v in search("youtube.search", {"query": brand, "uploadDate": "today"}, "videos", since):
        yield "youtube", v, v["title"], v["url"]


def main():
    seen = set(json.loads(SEEN.read_text())) if SEEN.exists() else set()
    since = time.time() - DAY
    for brand in BRANDS:
        for platform, item, text, url in mentions(brand, since):
            key = f"{platform}:{item['id']}"
            if key in seen or item.get("createdUtc", since) < since:
                continue
            seen.add(key)
            print(f"[{brand}] [{platform}] {' '.join(text.split())[:100]}\n  {url}")
    SEEN.write_text(json.dumps(sorted(seen)))


if __name__ == "__main__":
    main()
Three details in it come from what the test runs returned:
output.get("data") or {}. When a Reddit search runs out of results, the last page can come back withdataset to null instead of an empty list. It's still billed as a call.- The
createdUtccheck. Paging stops once a page reaches past the last 24 hours, so the final page usually carries a few older posts. The script drops them rather than printing yesterday's news. item.get("createdUtc", since). One YouTube result in the run, a stream, came back with no date at all. The script keeps it instead of crashing.
Run it once a day from cron and send the output wherever your team reads things:
0 8 * * * cd ~/listener && ANYAPI_API_KEY=your_key python3 listen.py >> mentions.logHere's everything the second run printed on 2026-09-30, nine minutes after the first. It only prints what the first run hadn't:
[supabase] [reddit] My planned migration window was 7 hours, and 5 of them went to data scripts, not to deploying code
  https://www.reddit.com/r/SaaS/comments/1wu2jud/my_planned_migration_window_was_7_hours_and_5_of/
[supabase] [reddit] If your Lovable app takes Stripe payments, check whether people who cancelled still have access
  https://www.reddit.com/r/lovable/comments/1wu2emq/if_your_lovable_app_takes_stripe_payments_check/
[supabase] [x] It has never been cheaper to build the company you've been cooking up in your head: Free coding agen
  https://x.com/i/web/status/2105423653978722520
[supabase] [x] Did you know you can fully self-host @supabase? 🚀 One command gets you Postgres, auth, S3-compatible
  https://x.com/i/web/status/2105422951675994375
[supabase] [x] @supabase anytime soon to fix the technical issues?
  https://x.com/i/web/status/2105421325292749231
[supabase] [x] https://t.co/XL4vyk0xjy
  https://x.com/i/web/status/2105085705496195252
[supabase] [x] The app/website is working and I have literally no idea how. I understood on Lovable. But now Im usi
  https://x.com/i/web/status/2105066033942020466
[supabase] [youtube] I built a $120K business in 60 minutes with Claude Code (live, no edits)
  https://www.youtube.com/watch?v=dKCi8yHfCmw
[supabase] [youtube] Implementasi Supabase pada Portfolio Website | Next.js | Muhammad Abyan Sudjatmiko | smkn1pasuruan
  https://www.youtube.com/watch?v=fAuCBarYdTY
How many brand mentions does X return, and why filter out replies?
X returned more mentions than Reddit and YouTube combined for every brand in the September 30, 2026 run. Across the three brands, that's 245 tweets in a day against 102 Reddit posts and 50 videos. Supabase took seven pages of 20 to get back through 24 hours.
Most of what X search returns for a product name is replies inside other people's threads. With no filter, 19 of the first 20 tweets for Supabase were replies, and those 20 covered only the previous 75 minutes. Adding -filter:replies to the query cut all of them: none of the 280 tweets the run pulled were replies. If you do want replies, keep them, and expect your page count to go up with them.
Half the tweets the run pulled came from accounts with fewer than 528 followers. Most were in English, with Japanese a distant second.
How much of what Reddit search returns is about your brand?
Reddit search was the cleanest of the three sources apart from crossposts: 91% of the Reddit posts, 93 of 102, named the brand in their title or body. The rest didn't have the name anywhere in the text the response carries.
The noise on Reddit is repetition. People who launch a side project post the same thing to two or three subreddits, usually within minutes, and each copy has its own ID. In the Supabase results, 9 of the 79 posts were copies of an earlier post by the same author with the same title. The script prints each one. If that bothers you, add the author and title to the seen key for Reddit.
Many of Supabase's Reddit mentions were builders showing off projects. The top subreddits were r/SideProject with 10 posts, r/saasforsale with 6, and the brand's own r/Supabase with 5.
Why does YouTube search return videos that don't mention your brand?
YouTube search is the weakest of the three sources, because its page fills up with videos that match the word but not the product. Only 8 of 50 YouTube results had the brand name in the title. For Raycast it was 2 of 20, and the rest included game-dev videos about raycasting, anime music videos and a physics explainer. For PostHog it was 1 of 10.
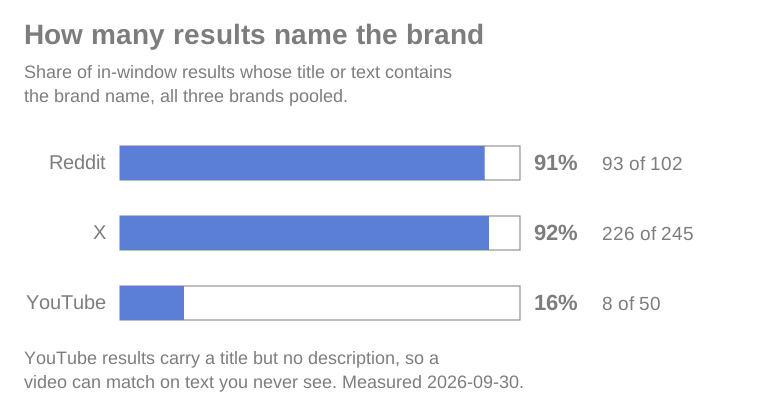
| Platform | Results in the last 24 hours | Name the brand | Share |
|---|---|---|---|
| 102 | 93 | 91% | |
| X | 245 | 226 | 92% |
| YouTube | 50 | 8 | 16% |
Some of those videos may mention the brand in the description, but the search result doesn't include a description, so you can't check without another call per video. Supabase and Raycast came back with 20 videos each and PostHog with 10, so the count says little about how much was actually posted.
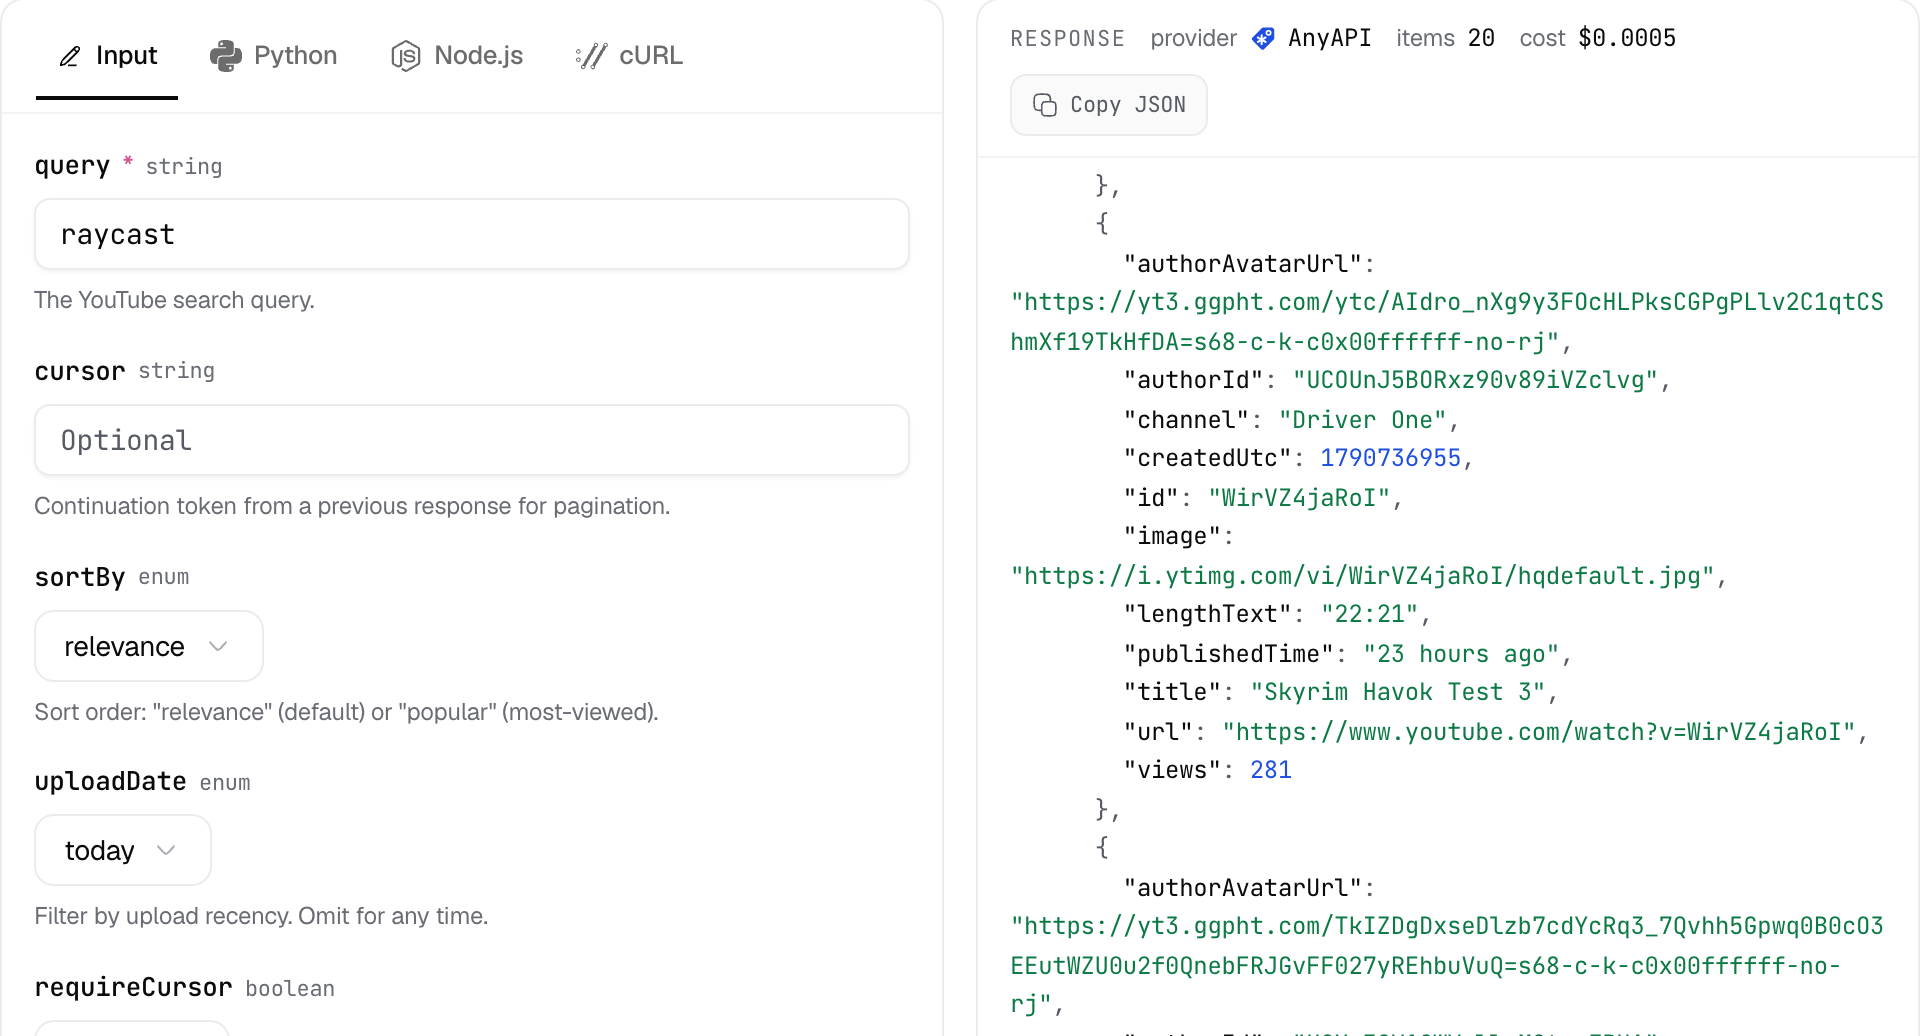
A rerun of the Raycast search in our playground the same evening returned 20 videos again. 4 titles contained the word raycast, and only 2 of those were about the app; the others were a Fancade scripting tutorial and a Pokémon raycasting project.
Two more quirks. The upload date filter is loose: in one call, 3 of the 20 "today" videos were three and four days old. And dates are only as precise as YouTube's own "9 hours ago" label, so every video with the same label in a response had the same timestamp.
If YouTube matters to you, search for a phrase people would put in a title ("supabase tutorial", "raycast review") and keep only results whose title contains your brand. For an ambiguous word like Raycast, that filter is what keeps the game-dev videos out.
How often should you run a social listening script?
Run a social listening script once a day: on September 30, 2026, a second run nine minutes after the first got back 400 results, and 391 of them had already been printed. The second run made the same 25 calls and cost the same $0.013, for 9 new mentions.
The 9 new ones are the reason the script re-reads the whole day instead of asking only for posts since the last run. Three were tweets posted after the first run started. The other six were hours old: two Reddit posts from about 11 hours earlier, two tweets from 22 and 23 hours earlier, and two YouTube videos the first run's page of 20 didn't include. The first run's searches just hadn't returned them. A script that only asked for "since last time" would never have seen them.
Running it every hour re-reads the same day 24 times and pays for each read, and on these numbers most of those reads print almost nothing. If you want mentions faster than daily, shrink the window to match the schedule and accept that a post one search skipped won't get a second chance.
How this compares to what is already published
A paid listening tool costs hundreds of dollars a month, and the official APIs each cover one platform. Prices below are from each vendor's page on September 30, 2026.
| Option | Price | Sources | What you get | Tested here |
|---|---|---|---|---|
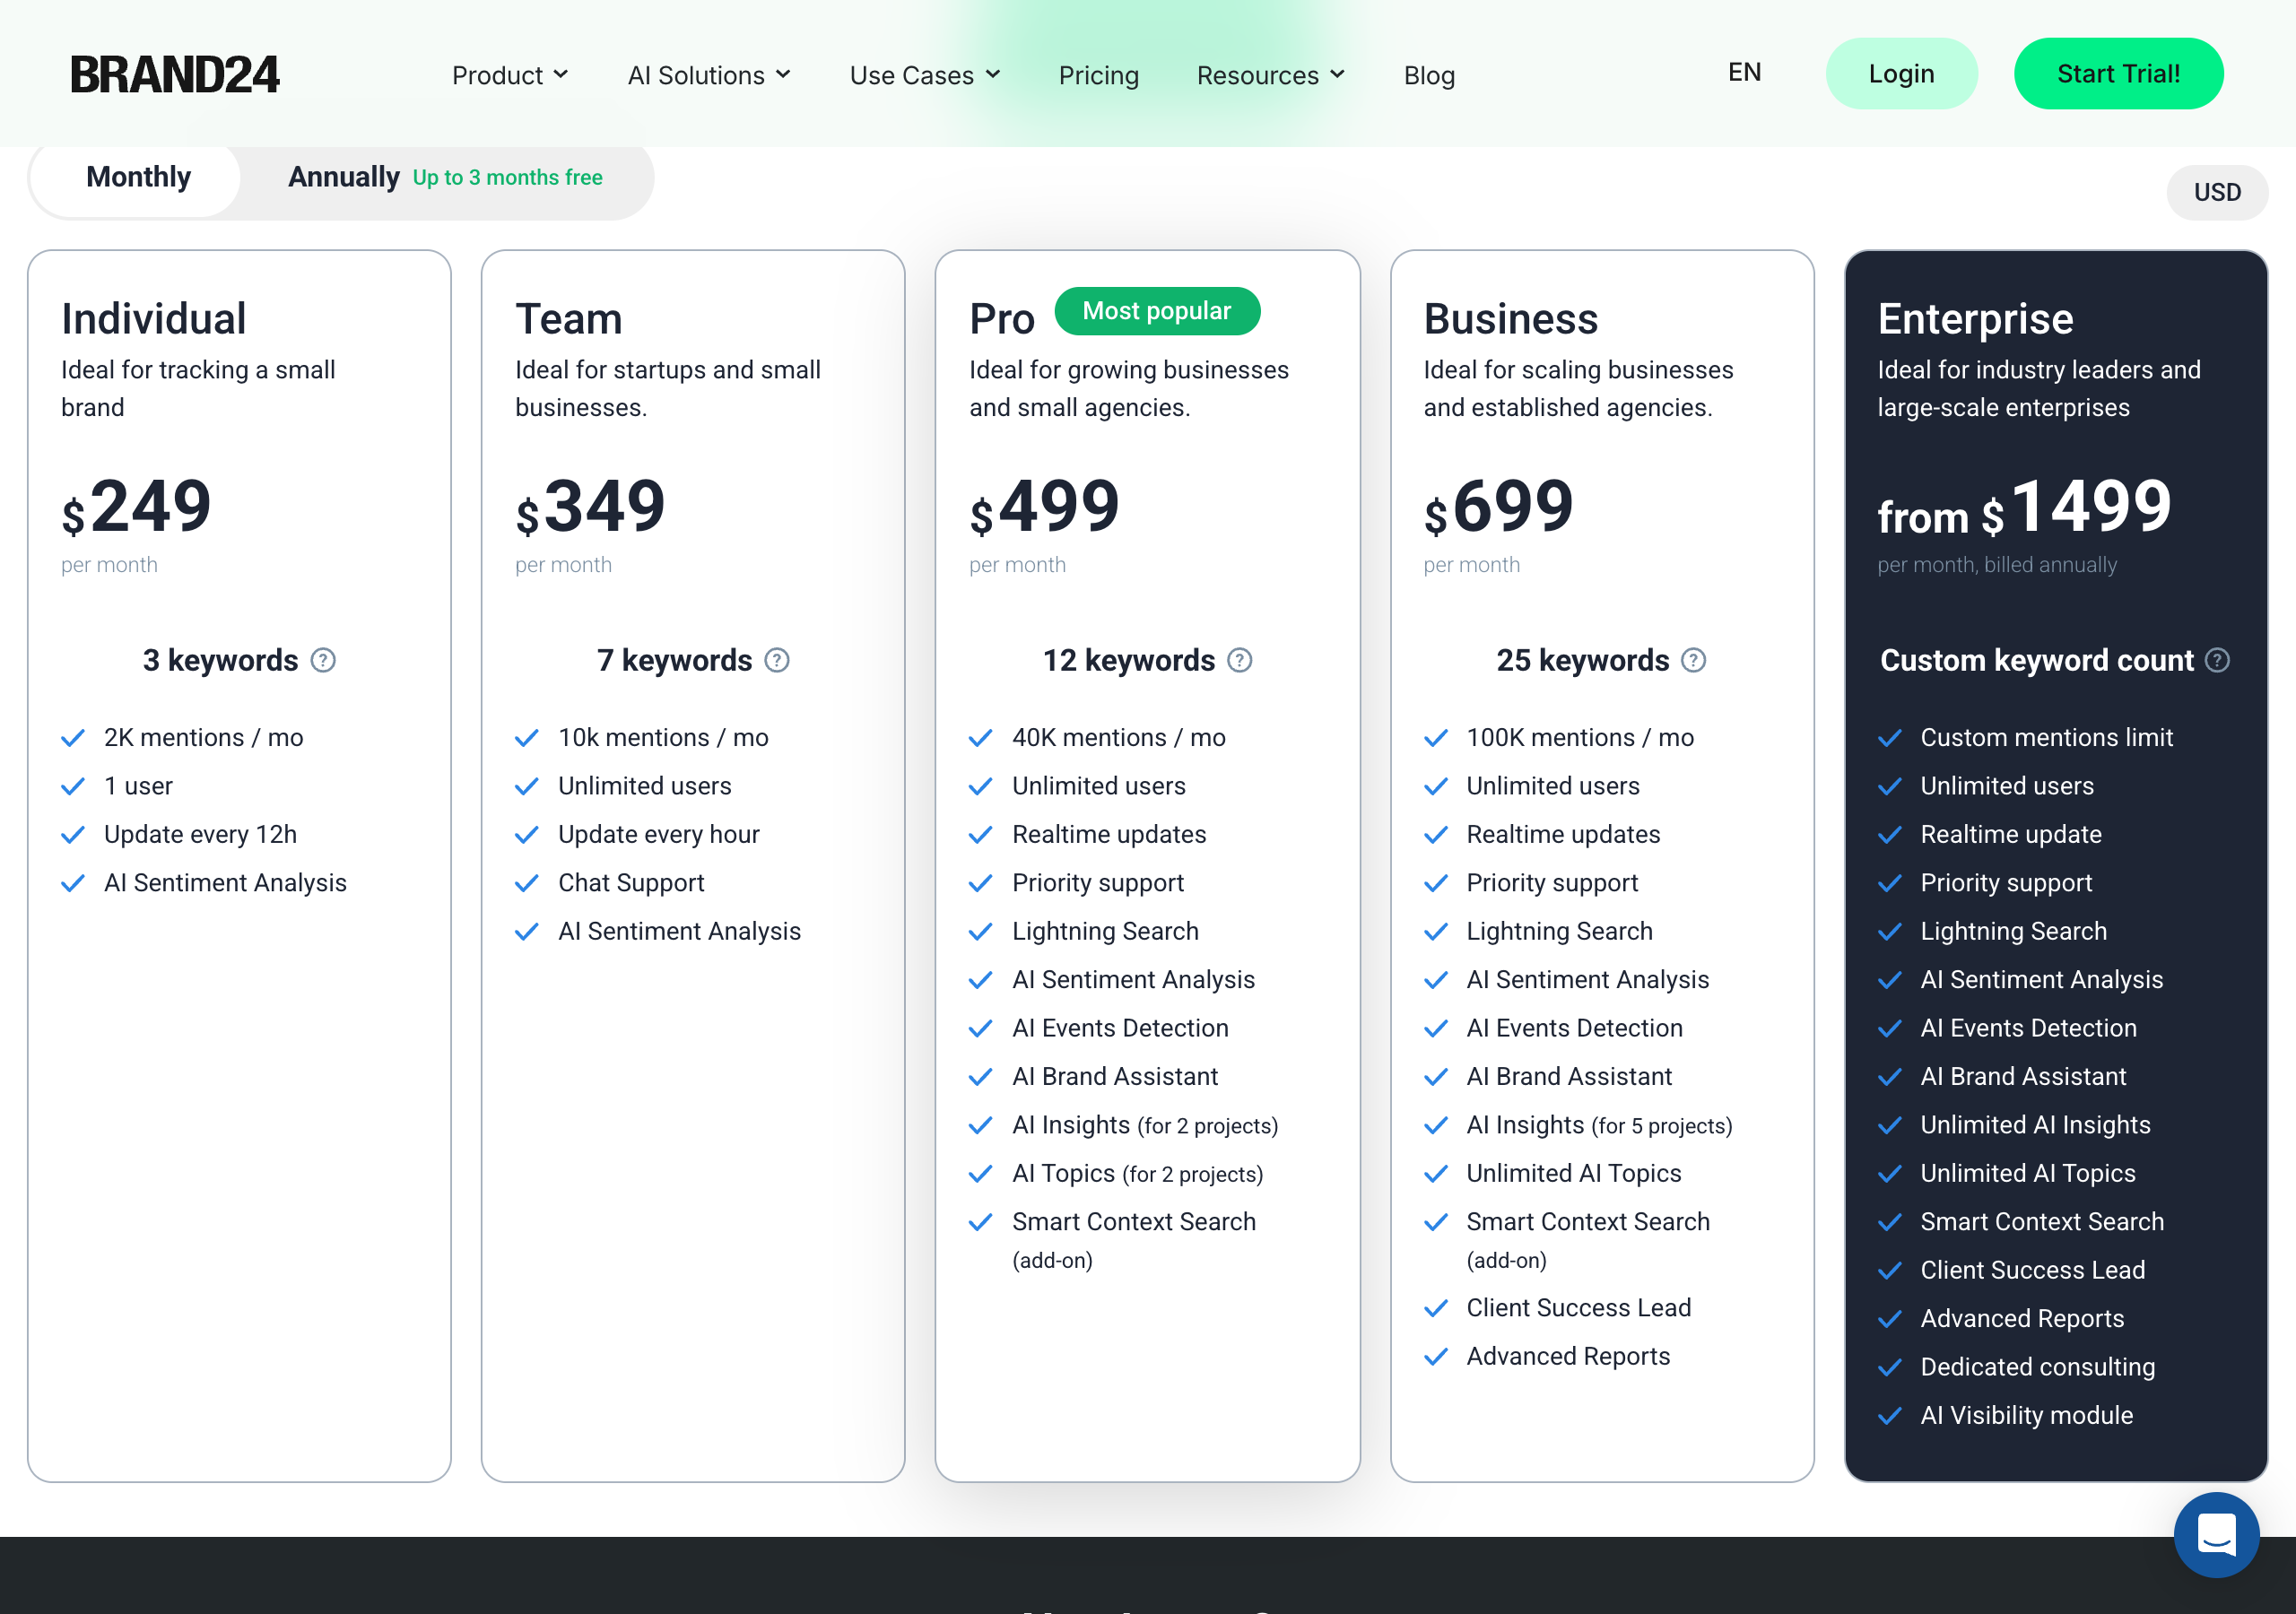
| Brand24 Individual | $249 a month billed monthly, $199 billed yearly | Reddit, X, YouTube and 9 more | 3 keywords, 2,000 mentions a month, updates every 12 hours, AI sentiment | Pricing page only |
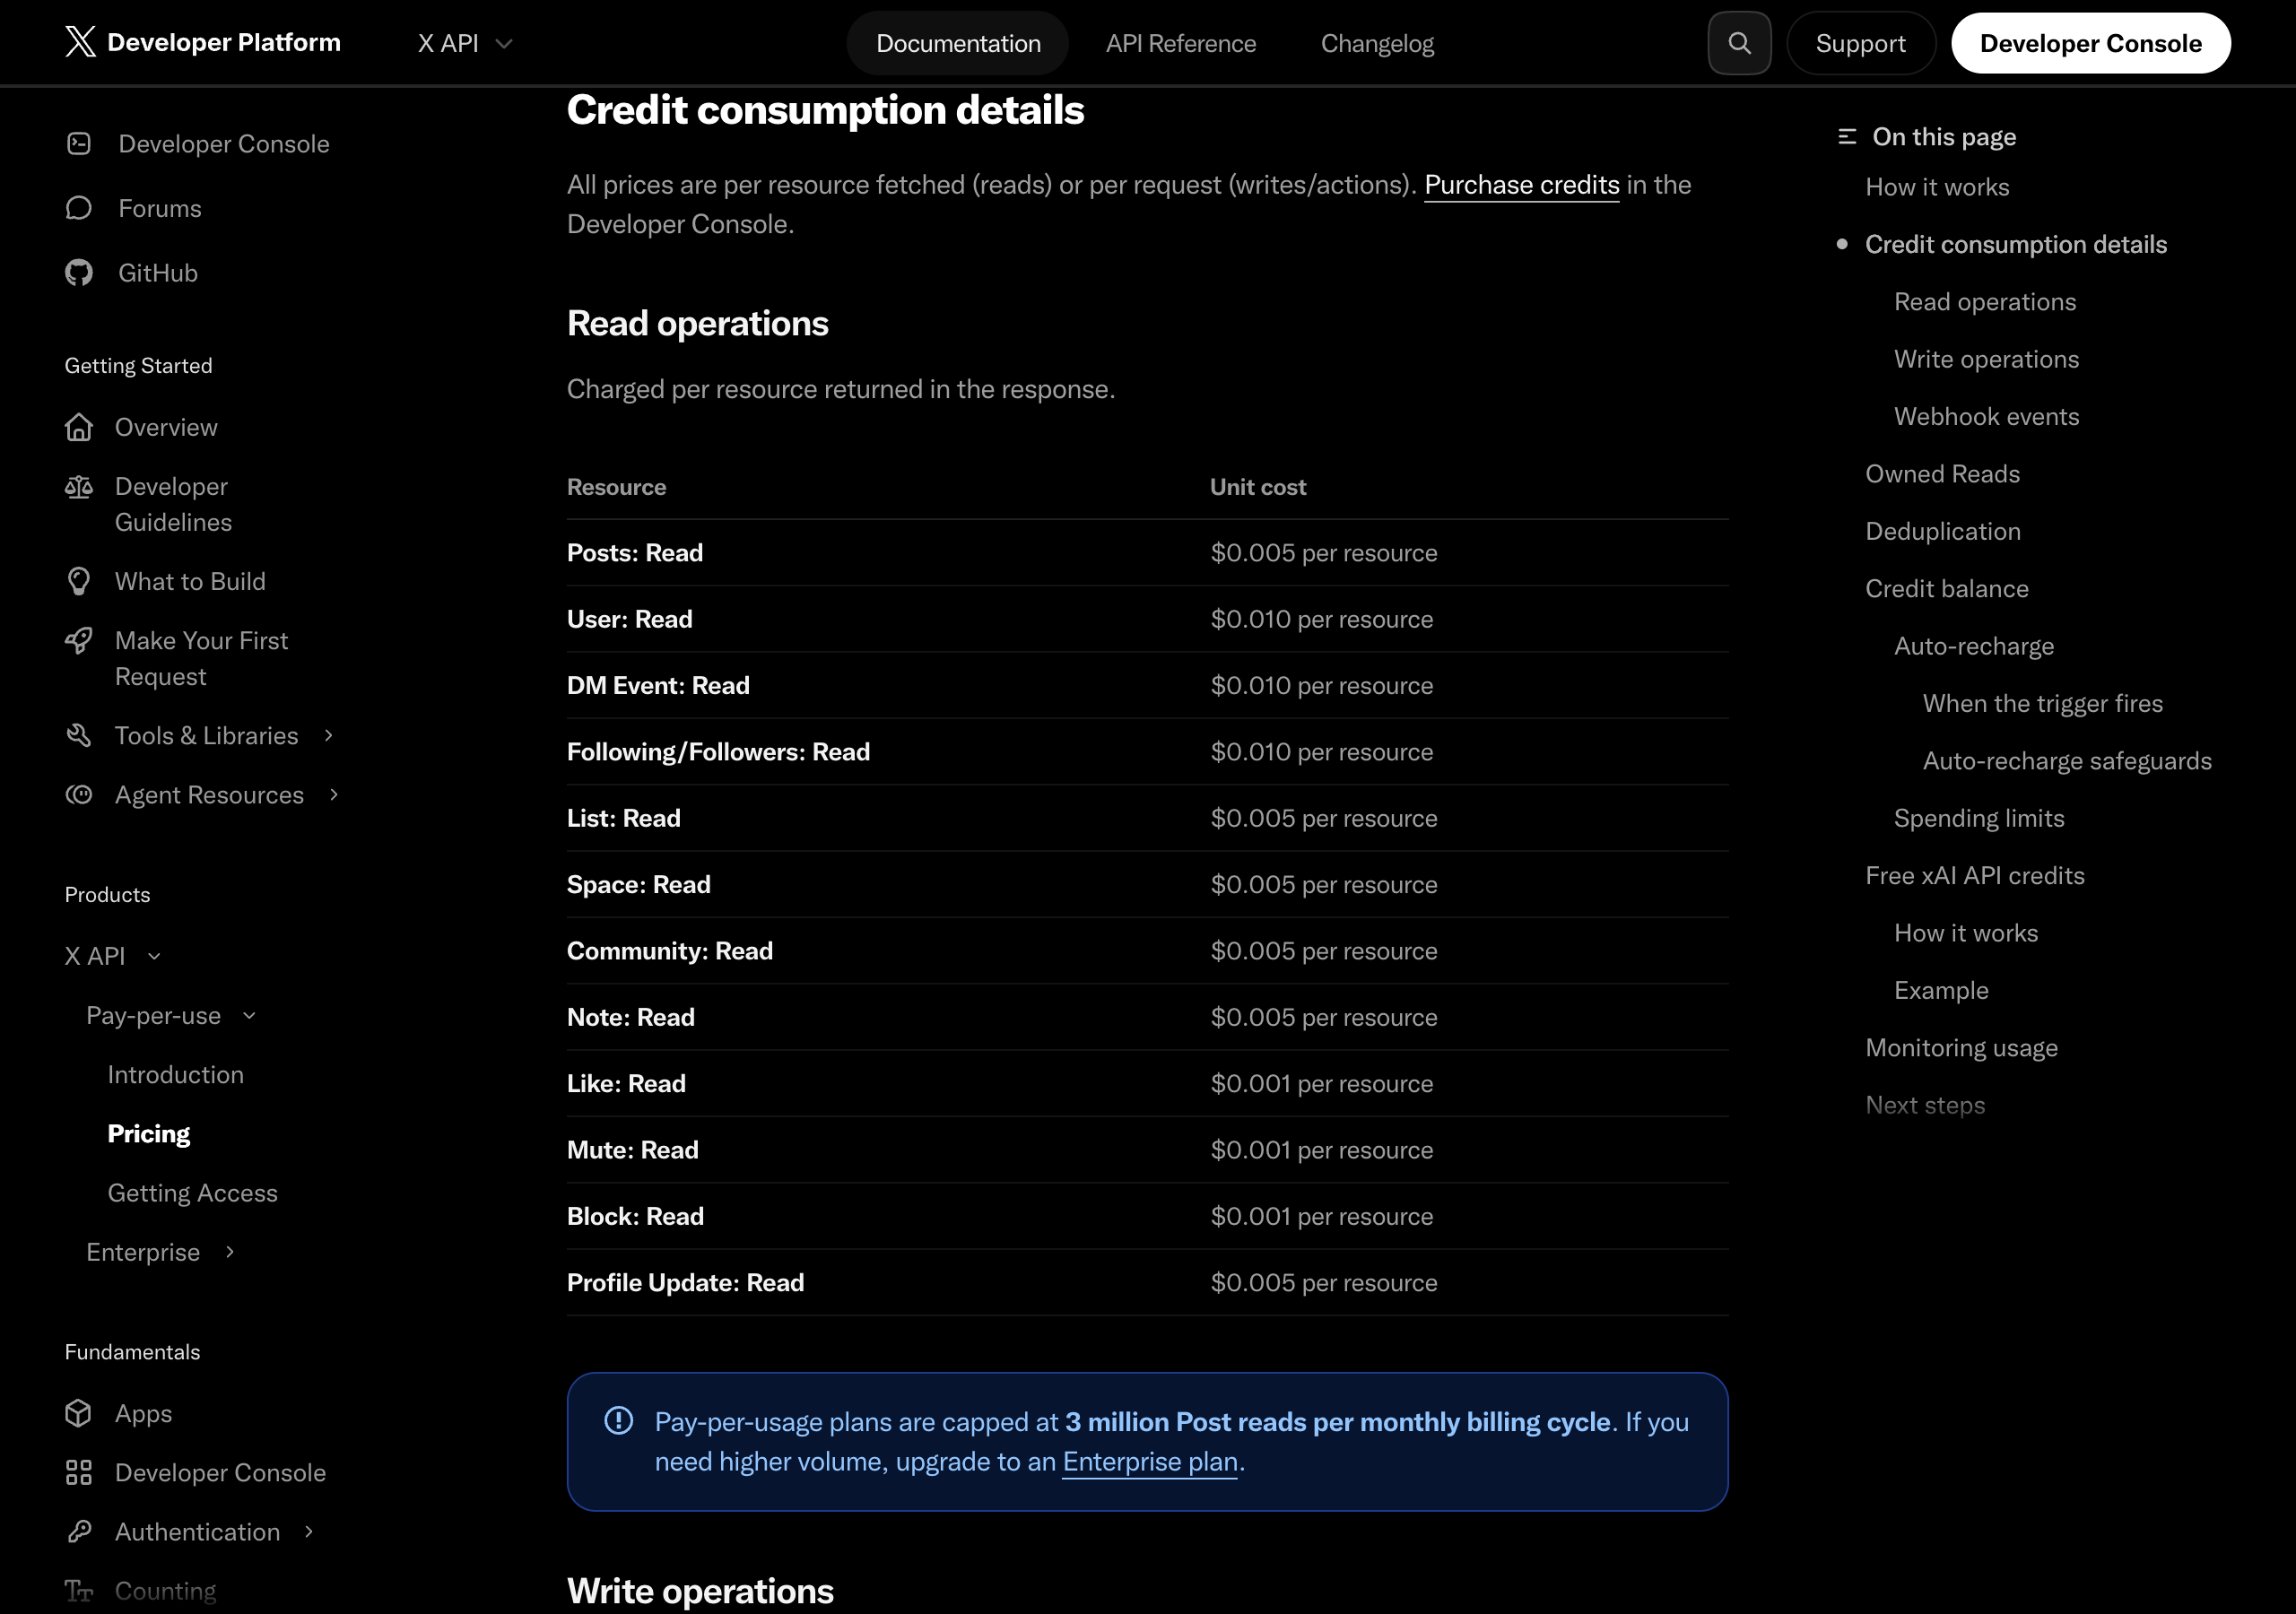
| X API | $0.005 per post read | X | Raw posts | Pricing page only; the 280 tweets here would be $1.40 |
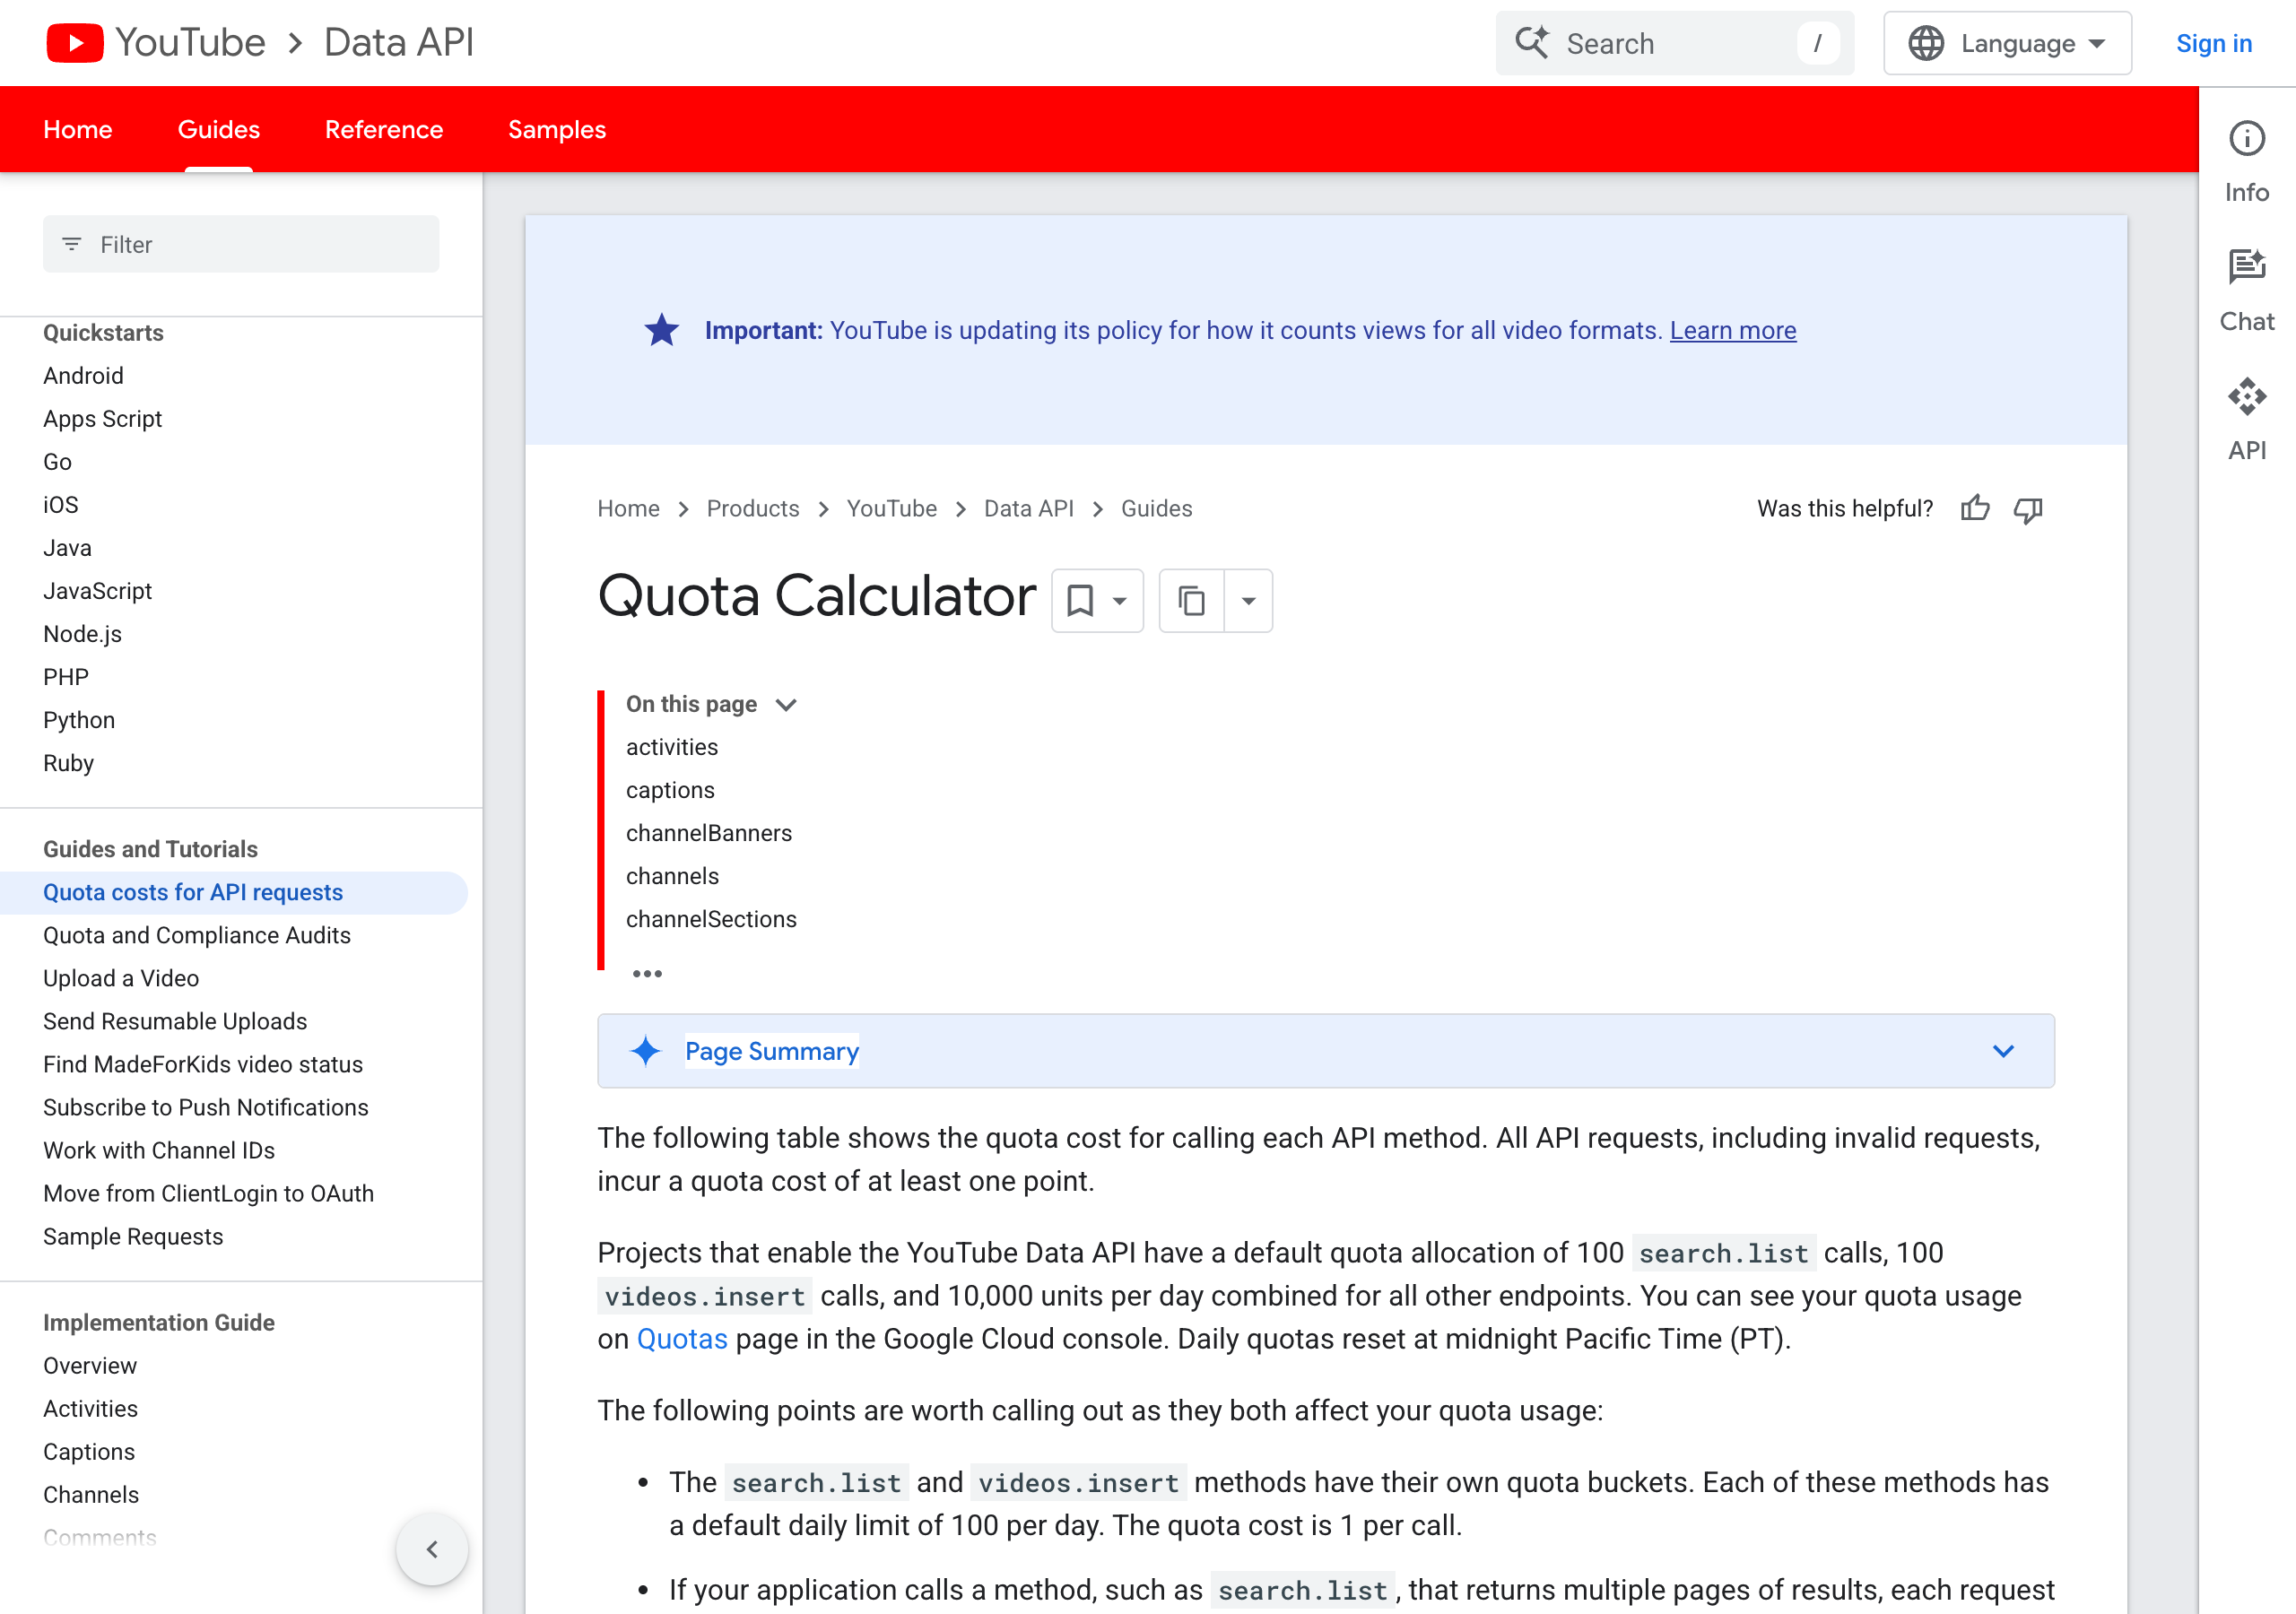
| YouTube Data API | 100 search.list calls a day free | YouTube | Raw search results | Quota page only |
| Reddit API | Free for non-commercial use, app approval required | Raw posts | Not tested | |
| The script on AnyAPI | Per 1,000 calls: Reddit $0.38, X $0.60, YouTube $0.50 | Reddit, X, YouTube | Raw mentions, no sentiment or history | 25 calls, 397 mentions, $0.013 a run |
- Brand24 lists Reddit, X and YouTube among its sources, and its Individual plan caps you at 2,000 mentions a month. At the rate this run found them, three brands would use that up in about five days.
- The X API charges per post read, so the 280 tweets this run pulled would be $1.40 there. It doesn't charge twice for the same post read within one UTC day.
- The YouTube Data API gives each project 100
search.listcalls a day for free. That's plenty for a few brands, and it's where to go if YouTube is all you want.
- Reddit's own API has a free tier for non-commercial use, with approval now required for new apps. Is the Reddit API free? has the details.
The listening tools are selling something different. You pay for sentiment scoring, dashboards, alerts, history and a team seat, and you get a lot more sources than three. The script gives you the raw mentions from three places and nothing on top. If you'd open Brand24 every day and read the sentiment graph, buy Brand24. If you'd pipe the mentions into Slack and read them there, the script does that.
How I measured it
The sample is 3 brands on 3 platforms: 25 calls on September 30, 2026 between 22:14 and 22:16 UTC, returning 397 unique results from the previous 24 hours, then the same 25 calls again from 22:25 UTC. Both runs used the script above, wrapped so every raw response was saved to disk and each figure could be recounted. The first run collected results without printing; the second ran the script as published. It went through three AnyAPI endpoints, reddit.search, twitter.search and youtube.search.
- Pick three brands with different volumes. Supabase, PostHog and Raycast, all developer tools. Raycasting is also a game-rendering technique, which tests how each platform handles an ambiguous name.
- Search each platform for the last 24 hours. Reddit sorted by new with the
daytime filter, X with replies filtered out, YouTube with thetodayupload filter. Reddit and X were paged until the results reached past 24 hours. YouTube's cheapest search returns one page with no cursor. - Count unique, in-window results. A result counts once per platform ID, and only if its timestamp is inside the 24 hours. Results with no timestamp count as in the window.
- Check whether each result names the brand. A case-insensitive match on the Reddit title and body, the tweet text, or the YouTube title.
- Run the script again, for real, nine minutes later. It started from the first run's seen list and printed only what was new.
The first run made 25 calls in 74 seconds and cost $0.013. The median call took 2.8 seconds. Checking the output shape, and two runs that stopped on the bugs the script now handles, took 21 more calls.
The limits of this data
- One day, three brands. The counts are one day's traffic for three developer tools. A consumer brand could get a very different mix.
- One repeat, nine minutes later. The share of repeats and late arrivals comes from a single pair of runs. A run twelve hours later wasn't measured.
- No sentiment. The script tells you a mention exists, not whether it's a complaint. You'd add that yourself, with a model or by reading.
- No history. The script only asks each search for the last day, so a new feed starts from yesterday. Listening tools sell backfill, and this script doesn't do it.
- It's search. Each platform's search decides what counts as a match. A post it doesn't index won't show up, and the script can't tell you what it missed.
- "Names the brand" is a text match. It misses a post that only links to your site and counts a post that uses the word for something else.
- Prices can change per call. Each endpoint falls back to a dearer source when the cheapest one fails. On X that can be up to $0.0154 a call instead of $0.0006.
A day of mentions for three brands is small data. It's enough to show the shape of each platform and not enough to say how often a given brand gets talked about.
What to do with it
- Start with the script as it is, once a day. It prints only what's new since the last run and cost about a cent a run here.
- Keep
-filter:replieson X unless you have a reason to read conversations. - Filter YouTube by title, and search for a phrase rather than a single word if your brand name means something else.
- Add author and title to the Reddit key if crossposts annoy you.
- Pipe the output into Slack or email rather than building a dashboard.
Per 1,000 calls, reddit.search is $0.38, twitter.search is $0.60, and youtube.search is $0.50.
Frequently asked questions
- What is a social listening API?
- A social listening API is a search endpoint you call on a schedule to collect new public posts that mention a brand, keeping a list of the IDs you've already seen. Three of them, for Reddit, X and YouTube, run once on September 30, 2026, found 397 mentions of Supabase, PostHog and Raycast from the previous 24 hours in 25 calls.
- Is there a free social listening API?
- Not one that covers Reddit, X and YouTube together. On September 30, 2026, YouTube's Data API gave each project 100 search.list calls a day for free, Reddit's API was free for non-commercial use once an app was approved, and the X API charged $0.005 per post read.
- How often should I run a brand mention script?
- Once a day, to match a 24-hour search window. In a test on September 30, 2026, a second run nine minutes after the first made the same 25 calls, got back 400 results, and found only 9 mentions the first run hadn't printed.
- How much does a social listening tool cost compared with a script?
- Brand24's cheapest plan, Individual, was $249 a month billed monthly on September 30, 2026, for 3 keywords and 2,000 mentions a month. A daily script that searches Reddit, X and YouTube for three brands made 25 calls a run and cost about a cent a run in a test the same day.
- Can I add sentiment analysis to a brand mention script?
- Yes, but you bring it yourself: send each new mention to a language model with a one-line prompt, or read them. The search endpoints return the mention text, author and date, not a sentiment score.
Want the full per-platform picture? Is the Reddit API free? covers Reddit's own API, and the Reddit MCP server post shows the same searches from an AI agent. Every search endpoint is in the catalog.
Every endpoint is priced in plain USD per call. New accounts start with free credit, no card required.
Run the three searches on your own brand
Use data responsibly and follow AnyAPI's Acceptable Use Policy.