Best ScraperAPI alternative for one price per page (2026)
- If you run a big, steady scraping operation and want async jobs, a pipeline that takes 100,000 URLs at once, and a vendor who'll bypass Cloudflare for ten more credits, ScraperAPI is built for you.
- If you want a page, a Google results list, or an Amazon product back at a price you can predict, pay per request: $0.50 to $0.90 per 1,000 calls on those endpoints, with no plan.
- ScraperAPI's plans start at $49 a month and were unchanged when checked on October 1, 2026. Credits reset when the plan renews, and a request costs 1 credit for a plain page, 10 to render it, 25 for Google, and 30 for LinkedIn.
- On eight test pages on September 13, 2026, ScraperAPI delivered 17 of 24 rendered fetches for 265 credits, two never came back, and the Cloudflare page got through once in three. AnyAPI delivered 42 of 48 for $0.035 and got through the Cloudflare page six times out of six.
- On 23 commonly scraped sites on October 1, 2026, one fetch each, 20 came back with the real page for $0.0237 in all. LinkedIn was $0.0007 a call, Amazon and Walmart $0.00125.
Built on AnyAPI
470 scraping and data APIs behind one key.
Every endpoint in this post is one call away. Pay per request in USD from a prepaid wallet, with automatic failover when a provider breaks. No subscription, no card to start.
Get ~160 free requests$0.10 of credit on signup.You buy ScraperAPI's $49 Hobby plan for its 100,000 credits, point it at Google, and find that a Google page costs 25 of them. Your 100,000 credits are 4,000 Google pages, and whatever's left resets to zero at renewal.
Eight test pages went through ScraperAPI, ScrapingBee, and AnyAPI on September 13, 2026, and ScraperAPI's plans were rechecked on October 1. Here's where ScraperAPI is the right choice, where paying per request wins, and what each job costs you.
Where is ScraperAPI strong?
If scraping is an operation you run rather than a call you make, ScraperAPI earns its place. It's one of the oldest scraping APIs still standing.
You send it a URL, and it fetches the page through rotating proxies, retries on failure for up to a minute, and gives you the HTML. On top of that it sells structured endpoints for Amazon, Walmart, eBay, Google, Redfin, and lately ChatGPT and Perplexity results.
For jobs you don't need back right away, there's an async API, and DataPipeline, a low-code tool that takes a list of up to 100,000 URLs and delivers the results. It bought Traject Data in April 2026, so the structured side is growing.
- It handles the jobs you'd rather not babysit. The async API takes a batch and works on it for up to 24 hours. DataPipeline takes a list of URLs, ASINs, or keywords, up to 100,000 at a time, and delivers HTML, JSON, or CSV on a schedule.
- It tries hard. ScraperAPI retries a failing request for up to 60 seconds before it gives up, its docs put the average success rate around 98%, and it only bills a 200 or a 404.
- It'll get through the hard sites, for a price. Premium proxies at 10 credits, ultra premium at 30, and a named bypass for Cloudflare, Turnstile, DataDome, and PerimeterX at 10 credits each. The
max_costparameter caps what any one request can spend. - Structured endpoints keep coming. Amazon, Walmart, and eBay products and searches, Google search, news, jobs, shopping, and maps, Redfin listings, and results from ChatGPT, Perplexity, Gemini, and Google AI Mode.
- The plan comes with throughput. 20 concurrent threads on Hobby, 300 on Professional, and geotargeting to 80-plus countries from the Business plan up.
ScraperAPI cons:
- Credits reset to zero at renewal
- 25 credits a Google page, 30 a LinkedIn page
- Bills a 404, and a request you cancel before 70 seconds
- A 13.2 second rendered median in the September test
If you run batches of thousands of URLs on a schedule and want someone else to own the retries, ScraperAPI is a sensible buy. If you make calls for data, keep reading.
ScraperAPI pricing: 7-day trial with 5,000 credits, then 1,000 free a month; Hobby $49 for 100,000 credits (a Google page is 25 of them, and leftovers reset at renewal); up to Professional at $975
Where does paying per request win?
If you make calls rather than run jobs, the per-site credit table is the whole problem, and the plan is the second one.
What does a credit buy on each site?
A credit is ScraperAPI's unit of spend, and each site you hit has its own price in credits. A plain page is one credit.
Rendering it, which means loading it in a real browser so prices or reviews drawn by scripts show up, is ten.
An Amazon page is five, a Google page twenty-five, a LinkedIn page thirty, and a site behind Cloudflare or DataDome adds ten on top.
ScraperAPI's pricing is five monthly plans: Hobby at $49 for 100,000 credits and 20 threads, Startup at $149 for a million and 50 threads, Business at $299 for three million and 100 threads, Scaling at $475 for five million, and Professional at $975 for 10.5 million.
Yearly billing takes 10% off. Credits you don't use reset when the plan renews, per ScraperAPI's own FAQ.
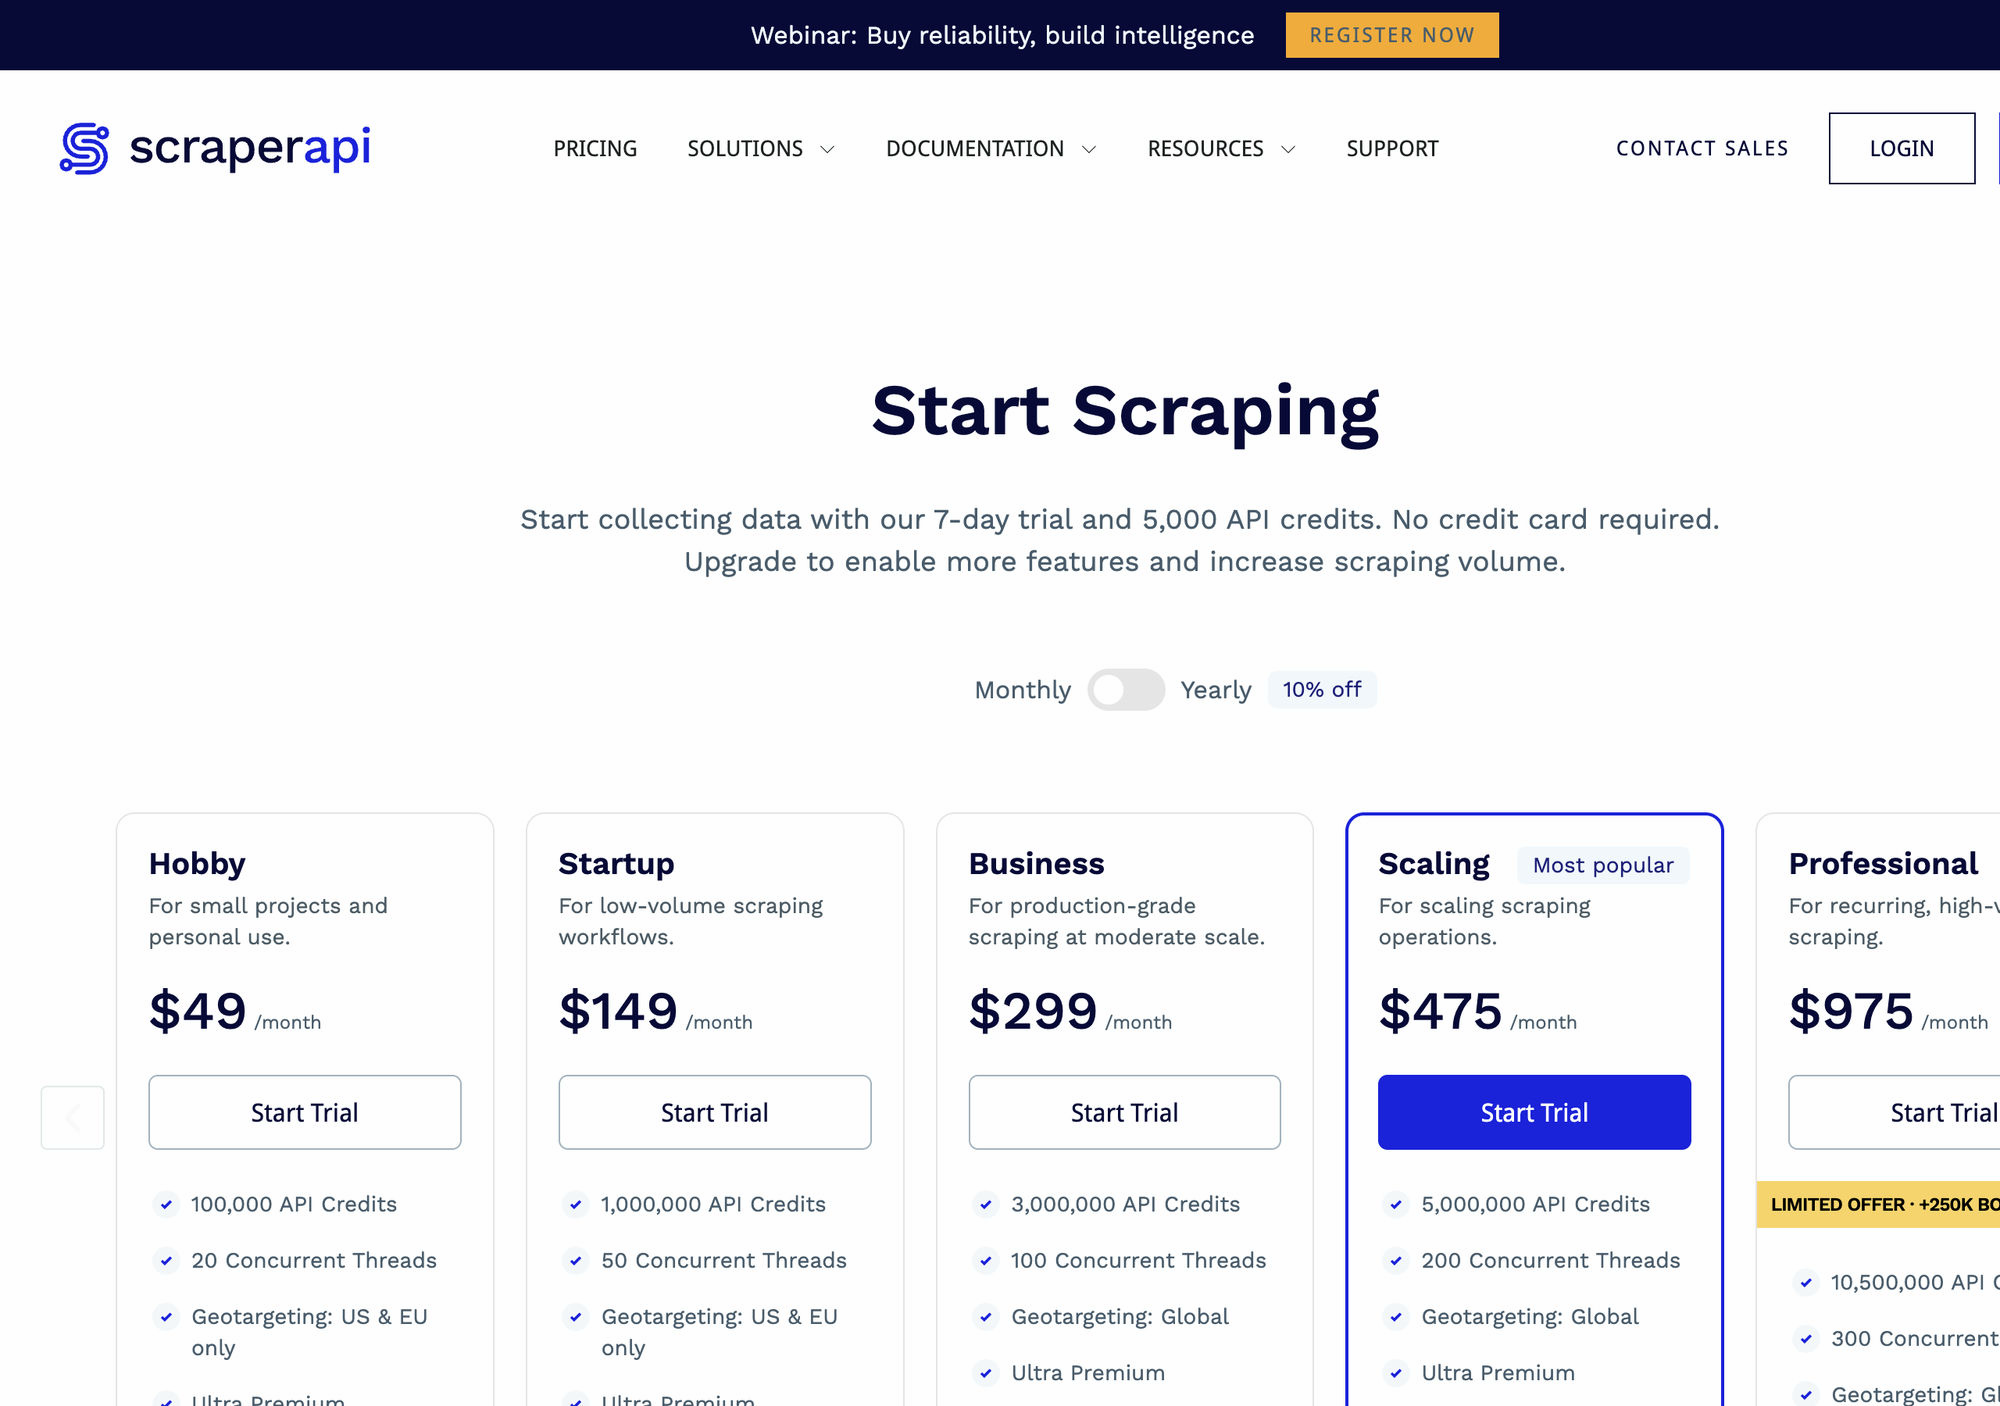
The credit table is where the price hides. On Hobby, you pay $0.49 per 1,000 for a plain page, but $4.90 for a rendered page, $2.45 for an Amazon product, $12.25 for a Google results page, and $14.70 for a LinkedIn page.
Startup halves and then some, but the shape is the same: the sites you actually want cost 5 to 30 times the listed price.
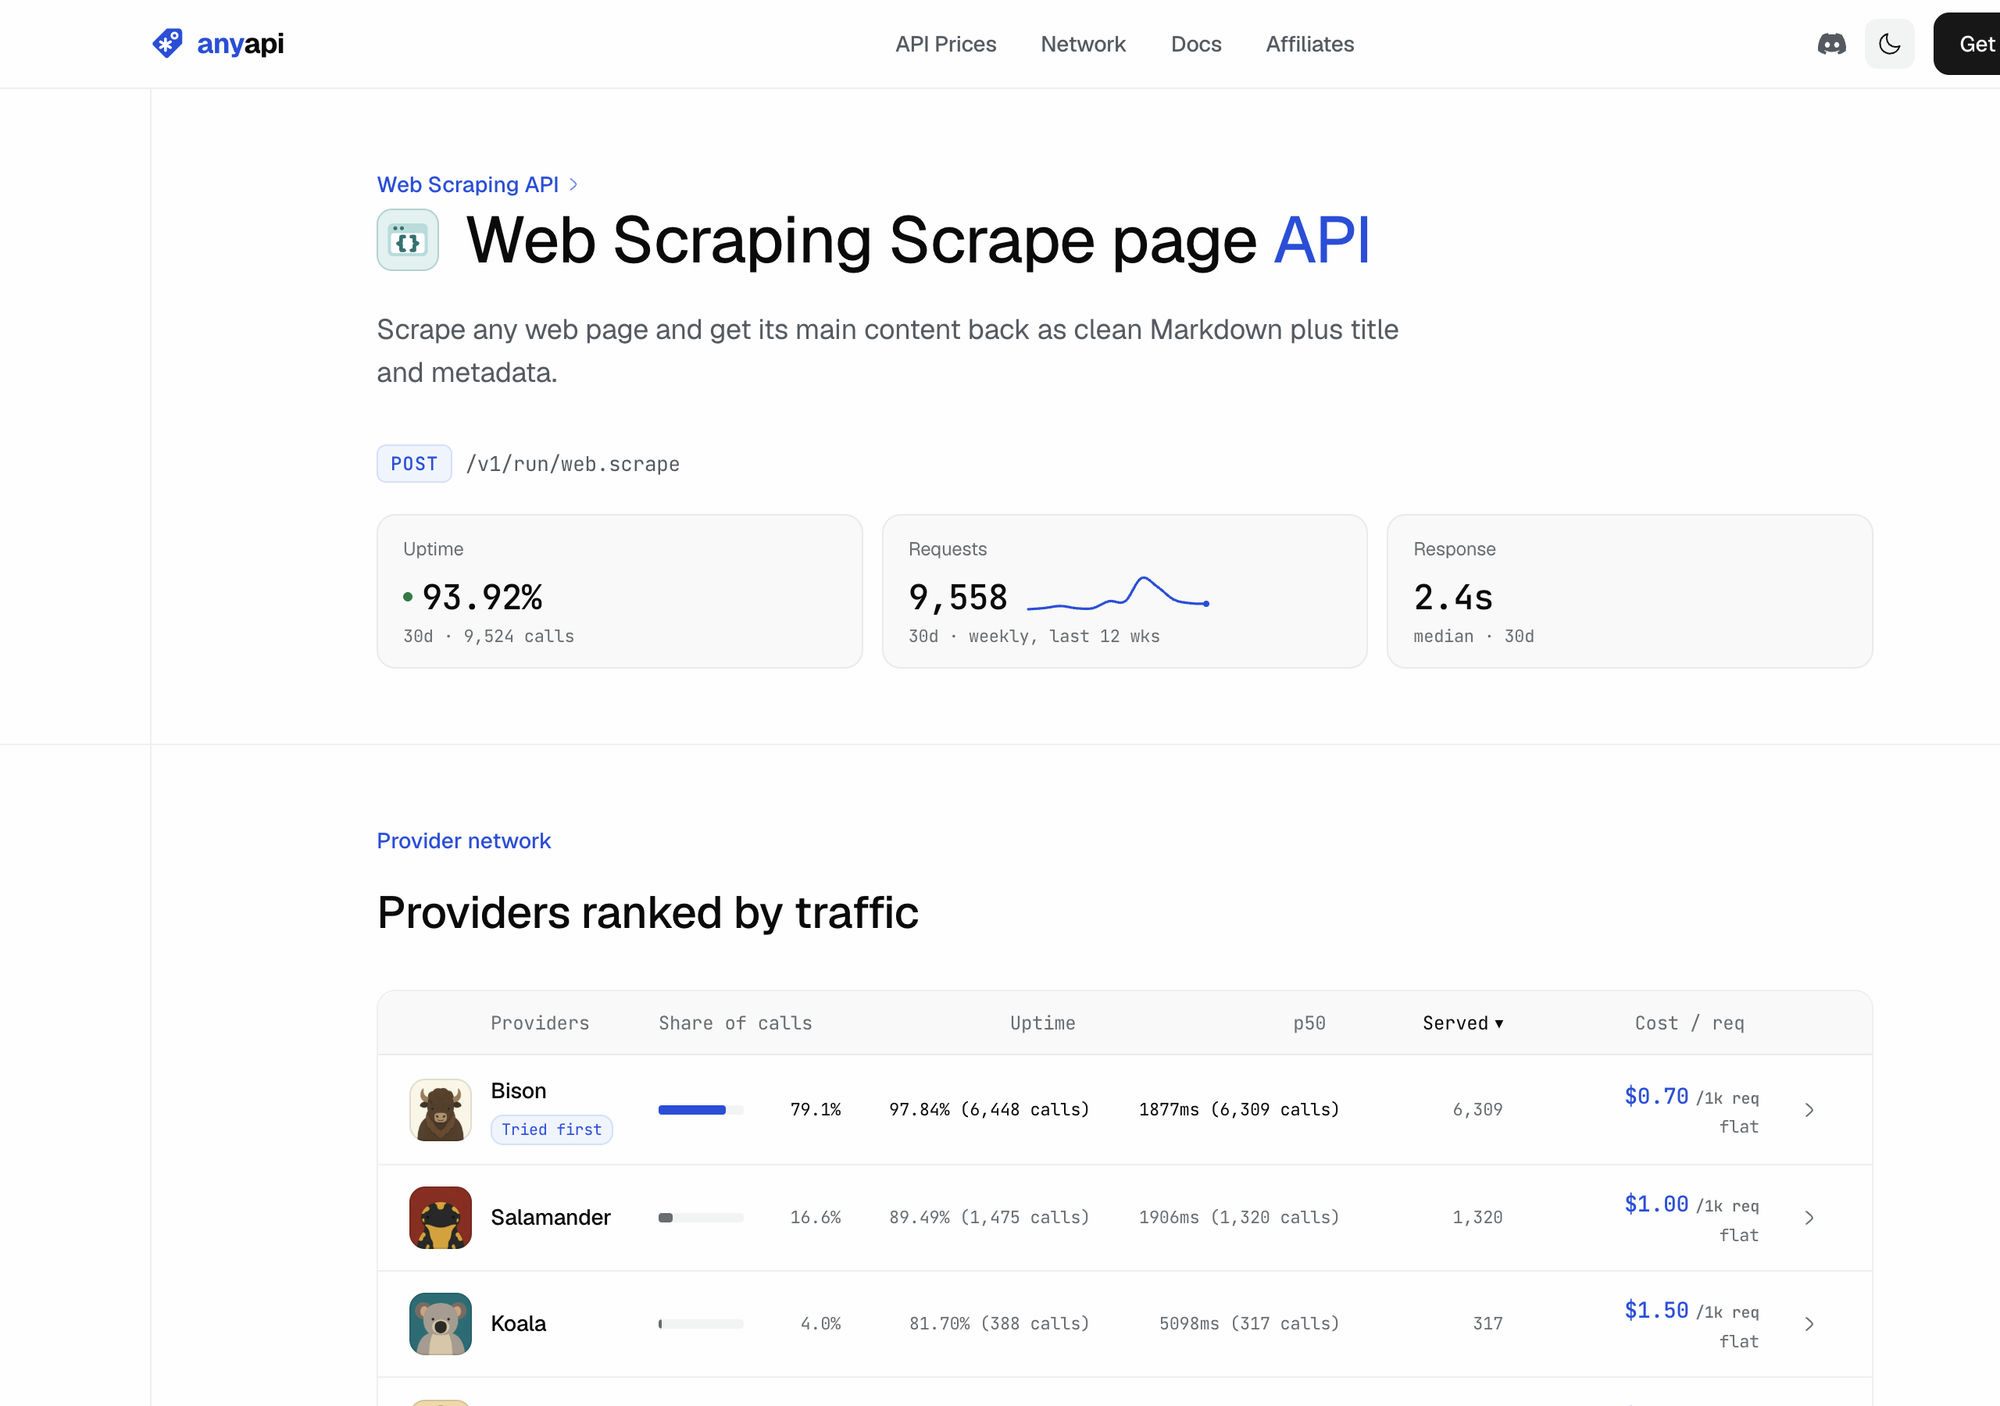
Paying per request, you see one price on the endpoint page, and it doesn't change with the plan, because there's no plan. A rendered page is $0.70 per 1,000, a Google results page $0.50, an Amazon product $0.90, an Amazon search $1.30, a LinkedIn company $1.10.
A month with no calls costs you $0 instead of $49.
Do you want the page, or the data on it?
If you want the page, ScraperAPI's plain endpoint returns HTML, and its structured endpoints cover the stores and Google. Everything else you parse yourself.
If you want the data, AnyAPI's catalog is 409 endpoints, most of them the platforms a scraping API gets used for: an Instagram profile at $1.00 per 1,000, a TikTok profile at $0.40, a LinkedIn profile at $2.90, a Reddit search at $0.35, a YouTube transcript at $0.90, a Google results page at $0.50.
You get one key, one request shape, one JSON envelope, and a response that tells you what the call cost.
What happens when a page fails?
If a person is waiting on your scrape, failures cost you time before they cost you money. ScraperAPI's docs say to expect latencies of 4 to 12 seconds and 1 to 3% of requests to fail unbilled.
In a June test of ScraperAPI against ScrapingBee, you'd have waited a median 13.5 seconds for a rendered page. The requests that failed took 36 to 57 seconds to do it, because it retries internally before it gives up.
AnyAPI's page scraper gives you fallback instead: it has four sources, the cheapest goes first, and a miss moves to the next one. Forty-eight test fetches had a 1.5 second median, and a page that fails on every source costs nothing.
A page that comes back is billed at the price of the source that returned it, never more than $1.50 per 1,000.
What does one call look like?
Here's what a Google results page costs you the pay-per-request way: nine results as JSON for $0.0004 in 9.9 seconds on September 27, 2026.
On ScraperAPI's Hobby plan the same page is 25 credits, or 1.2 cents.
curl https://api.getanyapi.com/v1/run/google.search \
  -H "Authorization: Bearer $ANYAPI_KEY" \
-d '{"query": "best web scraping api"}'import os, requests
r = requests.post(
"https://api.getanyapi.com/v1/run/google.search",
headers={"Authorization": f"Bearer {os.environ['ANYAPI_KEY']}"},
json={"query": "best web scraping api"},
)
body = r.json()
print(body["costUsd"], len(body["output"]["data"]["results"]))
# 0.0004 9const r = await fetch("https://api.getanyapi.com/v1/run/google.search", {
method: "POST",
headers: { Authorization: `Bearer ${process.env.ANYAPI_KEY}` },
body: JSON.stringify({ query: "best web scraping api" }),
});
const { costUsd, output } = await r.json();
console.log(costUsd, output.data.results.length); // 0.0004 9If you swap google.search for web.scrape and a URL, or amazon.product and an ASIN, the call is otherwise the same.
What happened on the same eight pages?
Eight pages, three rounds each, went through all three services on September 13, 2026: a static page, two scraping sandboxes, the Hacker News front page, an e-commerce sandbox, an Amazon product page, a G2 review page behind Cloudflare, and a Best Buy search.
JavaScript rendering was on everywhere, with the standard proxy tier on both credit vendors. A call counted only when the page's own text came back.
AnyAPI's column is two runs, so 48 calls.
| Page | ScrapingBee, rendered | ScraperAPI, rendered | AnyAPI web.scrape |
|---|---|---|---|
| Static page, two sandboxes, Hacker News, e-commerce sandbox | 15 of 15, 1.1 to 4.5 s, 5 credits each | 13 of 15, 6.8 to 43 s, 10 to 20 credits each; two calls never returned inside two minutes | 30 of 30, 0.9 to 2.8 s, $0.0007 each |
| G2 review page behind Cloudflare | 0 of 3: a 500 after 4.5 to 5.7 s, no charge | 1 of 3: 1.9 s and 30 credits when it worked, a 500 after 29 s when it didn't | 6 of 6, 1.2 s, $0.001 each |
| Best Buy search | 3 of 3, 2.4 to 4.5 s | 3 of 3, 14 to 20 s, 20 credits each | 6 of 6, 6.2 to 12 s |
| Amazon product page | 0 of 3: a 404, billed 5 credits | 0 of 3: a 404, billed 5 credits | 0 of 6: a "Continue shopping" wall as a 200, billed $0.0007 |
| Rendered pages delivered | 18 of 24 | 17 of 24 | 42 of 48 |
| Credits or dollars for the 24 rendered calls | 105 credits, $0.03 on the Freelance plan | 265 credits, $0.13 on Hobby | $0.018 |
| Median on delivered pages | 2.2 s | 13.2 s | 1.5 s |
ScraperAPI's docs say to expect 4 to 12 seconds and a 1 to 3% failure rate. Rendered, it was slower than that, and you waited longer for the failures.
Three results decide the choice for you.
The Cloudflare page is the whole argument for fallback. ScraperAPI got through once in three at 30 credits, and the other two made you wait 29 seconds for a 500.
ScrapingBee's standard tier got a 500 from G2 every time and, to its credit, charged nothing. To get through, you'd need its stealth proxy at 75 credits a page.
AnyAPI's cheapest source missed it every time and the next one answered every time, for $0.001 a page instead of $0.0007, and you don't change a setting.
Rendering is where ScraperAPI's credits go. A rendered page cost 10 credits on the sandboxes and 20 on the static page and the Best Buy search. So the same 24 calls that cost you 105 credits on ScrapingBee cost 265 on ScraperAPI, and two of them never came back inside two minutes.
ScrapingBee's rendered pages were 5 credits every time, which matches the June test. Speed followed the same order, 1.5 seconds on AnyAPI, 2.2 on ScrapingBee, 13 on ScraperAPI rendered, but if you're choosing on cost, the credits are the bill.
A 404 is billed on both credit vendors. Amazon answered the product URL with a 404 for both, and both charged 5 credits for a page you didn't get.
AnyAPI's source got a 200 with a "Continue shopping" wall, and AnyAPI charged $0.0007 for it.
Nobody got the product. If you're after Amazon products, the Amazon product endpoint at $0.90 per 1,000 is the call to make, not a page fetch.
Which commonly scraped sites come back, and at what price?
The eight pages above are a small test. So on October 1, 2026, 23 of the URLs people most often try to scrape went through AnyAPI's page scraper, one fetch per site, one call at a time: stores, property and job sites, review sites, social profiles, a paywalled news article, a Cloudflare test page, and Wikipedia as a control.
A call counted only when the page's own content was in the text, so a captcha or a paywall preview that came back as a 200 was a miss.
| Site, October 1, 2026 | Real page | Time | Charged | What came back instead |
|---|---|---|---|---|
| Zillow city search | Yes | 1.5 s | $0.00125 | |
| Cloudflare challenge test page | Yes | 2.5 s | $0.00125 | |
| Etsy search | Yes | 3.0 s | $0.00125 | |
| Craigslist listings | Yes | 3.2 s | $0.0007 | |
| X profile | Yes | 3.6 s | $0.0007 | |
| G2 product reviews | Yes | 3.6 s | $0.00125 | |
| Booking.com hotel | Yes | 3.6 s | $0.00125 | |
| Walmart product | Yes | 3.7 s | $0.00125 | |
| Wikipedia article (the control) | Yes | 4.2 s | $0.0007 | |
| Medium article | Yes | 4.2 s | $0.0007 | |
| Trustpilot company reviews | Yes | 4.6 s | $0.00125 | |
| Redfin city search | Yes | 4.7 s | $0.00125 | |
| LinkedIn company page | Yes | 4.7 s | $0.0007 | |
| Indeed job search | Yes | 4.8 s | $0.00125 | |
| Tripadvisor attraction | Yes | 5.2 s | $0.00125 | |
| Shopify store product | Yes | 5.5 s | $0.0007 | |
| Amazon product | Yes | 6.1 s | $0.00125 | |
| Reddit thread | Yes | 6.4 s | $0.0015 | |
| Instagram profile | Yes | 6.4 s | $0.0015 | |
| eBay search | Yes | 9.9 s | $0.00125 | |
| New York Times article | No | 4.0 s | $0.0015 | A paywall preview ("we are checking your access"), charged |
| Yelp business page | No | 16.5 s | Free | An error |
| Glassdoor company page | No | 23.4 s | Free | An error |
20 of the 23 sites came back with the real page. The median call took 4.6 seconds, and every page came back inside 10. The 23 calls cost $0.0237: the two errors were free, and the paywall preview cost $0.0015.
ScraperAPI's credit table prices these sites one by one: Amazon, Walmart, and eBay at 5 credits, LinkedIn at 30, any Google page at 25, and 10 more to render or to get past Cloudflare. On Hobby that's $2.45 per 1,000 for the stores and $14.70 for LinkedIn before rendering; here LinkedIn came back at $0.0007 a call and Amazon and Walmart at $0.00125.
Which other ScraperAPI alternatives are worth a look?
If you want to keep sending URLs but not ScraperAPI's credit table, its closest rivals sell the same thing: HTML back through someone else's proxies, on credit bundles with different multipliers. These are page reads, not runs, from their pricing pages on September 13, 2026, at the entry paid tier with every credit used.
| Service | How you pay | Entry price | Plain page, per 1,000 | Rendered page, per 1,000 | Free tier | Failed calls |
|---|---|---|---|---|---|---|
| ZenRows | Monthly credits, 1 month rollover | $19 for 45,000 | $0.42 | $2.11 | 5,000 credits a month | Free; 404 and 410 are billed |
| Scrapfly | Monthly credits | $30 for 200,000 | $0.15 | $0.90 | 1,000 credits | Free |
| Zyte API | Per request, priced by how hard the site is | None | $0.13 to $1.27 | $1.01 to $16.08 | $5 for 30 days | Free |
| ScrapingAnt | Monthly credits | $19 for 100,000 | $0.19 | $1.90 | 10,000 credits a month | Free |
| Crawlbase | Monthly plan or a balance that never expires | $99 for 200,000 | $0.50 | $0.99 | 5,000 requests | Free |
| Bright Data Web Unlocker | Per success, no minimum | None | $1.50 | $1.50 | 5,000 a month | Free, unless you set your own headers |
| Oxylabs | Monthly results | $49 | $1.15 | $1.35 | 2,000 results | Free |
AnyAPI web.scrape | Per call | None | $0.70, always rendered | $0.70 | A small starter balance | Free |
If you like the credit model and only hate credits that reset at renewal, ZenRows is the closest match.
Rendering costs 5 credits and a premium proxy 10. But unused credits roll over for a month, and you get 5,000 free credits every month against ScraperAPI's 1,000.
Skip it if rendered pages are most of your bill: on the $19 plan they're $2.11 per 1,000. Its pricing page shows the annual price until you click Monthly, so the $16 you'll see first is the yearly rate.
ZenRows pricing: 5,000 free credits a month; $19 for 45,000 credits (rendering is 5 credits a page; unused credits roll over one month)
If you want the cheapest rendered page on a plan, Scrapfly is the pick, at $0.90 per 1,000 on $30 a month. It also lets you cap what any request can spend with a cost_budget parameter.
Skip it if your targets block hard and you need to know the price first. Its anti-bot layer is free when the site isn't blocking and unpriced when it is.
Scrapfly pricing: 1,000 free credits; $30 for 200,000 credits a month (residential proxies with rendering are 30 credits, or $4.50 per 1,000, and the anti-bot price on a blocking site isn't published)
If your sites are easy and your volume is high, Zyte API is the best buy here.
It prices each request you send by how hard Zyte rates the site. A simple page is $0.13 per 1,000 and an advanced one $1.27, or $1.01 to $16.08 with a browser.
No plan, no minimum, failures free. The catch: you don't choose the tier, Zyte does, so on a hard site it's the worst buy in the table.
Zyte API pricing: $5 free for 30 days, then per request ($0.13 to $16.08 per 1,000, set by how hard Zyte rates the site)
If you want a free tier you can build on, ScrapingAnt gives you 10,000 credits every month. Paid starts at $19 for 100,000, with plain pages at $0.19 per 1,000 and rendered at $1.90.
Skip it if your sites block, because its multiplier table is the steepest here: a rendered page through a residential proxy is 125 credits, or $23.75 per 1,000.
ScrapingAnt pricing: 10,000 free credits a month; $19 for 100,000 (125 credits a page with rendering and a residential proxy)
If resetting credits are what you're leaving ScraperAPI over, Crawlbase has a balance that never expires.
Its ladder starts at $3.00 per 1,000 and falls to $0.50 at a million, alongside a $99 plan. Residential proxies and CAPTCHA handling come with every request.
The catch: if a site is hard, its difficulty tier multiplies what you pay by up to 20.
Crawlbase pricing: 5,000 free requests; a balance from $3.00 per 1,000, falling to $0.50 at a million (hard sites cost up to 20 times more); or $99 for 200,000 a month
Bright Data's Web Unlocker and Oxylabs are the enterprise pair.
If you fetch under 5,000 pages a month, Bright Data costs you nothing. Above that it's $1.50 per 1,000 whether or not the page needs a browser, the dearest plain page in the table, with unlimited concurrency.
If you mostly fetch Amazon, Oxylabs is a monthly results plan from $49, with Amazon pages at $0.50 per 1,000 and everything else at $1.15. The best Bright Data alternative covers that side of the market.
Bright Data Web Unlocker pricing: 5,000 a month free, then $1.50 per 1,000 (failures are free unless you set your own headers)
Oxylabs pricing: 2,000 free results; from $49 a month ($1.15 per 1,000 for most pages, $0.50 for Amazon)
The short version:
- Plain pages at volume: Zyte for easy sites, or Scrapfly on a plan
- A free tier you can build on: ScrapingAnt, or Bright Data's 5,000
- A balance that never expires: Crawlbase
- One price per rendered page with no bundle to fill: pay per request
ScraperAPI's other direct rival is priced in the best ScrapingBee alternative.
How do ScraperAPI and paying per request compare?
| What you deal with | ScraperAPI | Paying per request |
|---|---|---|
| What you're billed for | Monthly plan, 1 to 75 credits a request by site | The listed price per call, in USD; a page every source fails on is free |
| Subscription | $49 to $975 a month, credits reset at renewal | None |
| Plain page, per 1,000 | $0.49 on Hobby, $0.15 on Startup | $0.70, rendered |
| Rendered page, per 1,000 | $4.90 on Hobby, $1.49 on Startup | $0.70 |
| Google results page, per 1,000 | $12.25 on Hobby, $3.73 on Startup | $0.50, as JSON |
| LinkedIn page, per 1,000 | $14.70 on Hobby, $4.47 on Startup | $2.90 for a profile, $1.10 for a company |
| Sites behind Cloudflare or DataDome | +10 credits a request | Falls back to a dearer source |
| Async jobs and 100,000-URL pipelines | Yes | No, it's one call at a time |
| Pay as you go | Only on the $475+ plans | Always |
| A month you scrape nothing | Your plan price | $0 |
Limitations and what you give up
Running a scraping operation with batches, schedules, and hard targets? Stay on ScraperAPI. The async API, DataPipeline, the named bypasses, and the thread counts are what you need for an operation, and plain HTML at Startup's $0.15 per 1,000 is hard to beat.
Making calls for data? Pay per request. You get one price per endpoint and no credit table to reason about.
There's no plan that resets, and the sites you actually want are the same price as the easy ones.
AnyAPI cons:
- No batch or async mode, so a 100,000-URL job is 100,000 calls you make yourself
- A plain, unrendered page costs $0.70 per 1,000 against $0.49 on ScraperAPI's Hobby plan, because every page goes through a browser
AnyAPI pricing: $0.70 per 1,000 rendered pages and $0.50 per 1,000 Google results pages, with no plan (a page a dearer source rescues costs up to $1.50 per 1,000)
Before you pay anyone, check the free tiers. If you need under 1,000 plain pages a month, ScraperAPI's own 1,000 free credits a month already cover you, and Bright Data gives 5,000 pages a month for free.
If you're weighing ScraperAPI against its closest rival, see ScrapingBee vs ScraperAPI, tested and the best ScrapingBee alternative. If search results are your main job, the best SerpApi alternative prices that on its own.
Frequently asked questions
- How much does ScraperAPI cost in 2026?
- ScraperAPI's monthly plans are Hobby at $49 for 100,000 API credits and 20 concurrent threads, Startup at $149 for 1,000,000 and 50 threads, Business at $299 for 3,000,000 and 100 threads, Scaling at $475 for 5,000,000 and 200 threads, and Professional at $975 for 10,500,000 and 300 threads. Yearly billing is 10% off. New accounts get a 7-day trial with 5,000 credits, then 1,000 free credits a month. Checked October 1, 2026.
- How many credits does a ScraperAPI request cost?
- One credit for a normal request. JavaScript rendering is 10, a premium proxy 10, premium with rendering 25, ultra premium 30, ultra premium with rendering 75, and a screenshot 10. By site, Amazon, Walmart, and eBay are 5 credits, Google and Bing 25, and LinkedIn 30. Bypassing Cloudflare, Turnstile, DataDome, or PerimeterX adds 10 credits a request.
- Do ScraperAPI credits roll over?
- No. ScraperAPI's FAQ says the credit balance resets when the subscription renews. If you run out on Hobby, Startup, or Business, the options are to upgrade or ask for a custom plan. Pay-as-you-go overage is only available on the Scaling, Professional, Advanced, and Enterprise plans.
- Does ScraperAPI charge for failed requests?
- Not for a failed page, which comes back as an unbilled 500. It does bill a 404, so a missing page costs credits: on September 13, 2026, an Amazon product URL that came back as a 404 cost 5. It also bills requests you cancel before it's had 70 seconds to finish. It retries a failing request for up to 60 seconds before returning a 500, and its docs say to expect 1 to 3% of requests to fail.
- Is there a cheaper ScraperAPI alternative?
- For rendered pages and per-site data, yes. AnyAPI's web.scrape is $0.70 per 1,000 rendered pages against $4.90 on ScraperAPI's Hobby plan, and a Google results page is $0.50 per 1,000 as JSON against $12.25. For plain unrendered HTML at volume, ScraperAPI's Startup plan at $0.15 per 1,000 is cheaper.
Use data responsibly and follow AnyAPI's Acceptable Use Policy.